Deep dives into GPU infrastructure, inference optimization, and the future of AI compute.
Deploy OpenClaw and Ollama as two separate pods on Istidlal, connect them over public URLs, and run Qwen3.6 35B with no per-token costs and no context ceiling.
Eliminate the tedious setup and constant context switching required to run Jupyter notebooks on remote GPUs directly from VSCode using Istidlal extension
Deploy Nous Research's 405B-parameter Hermes 3 model efficiently using a 48GB GPU slice and FP8 quantization.
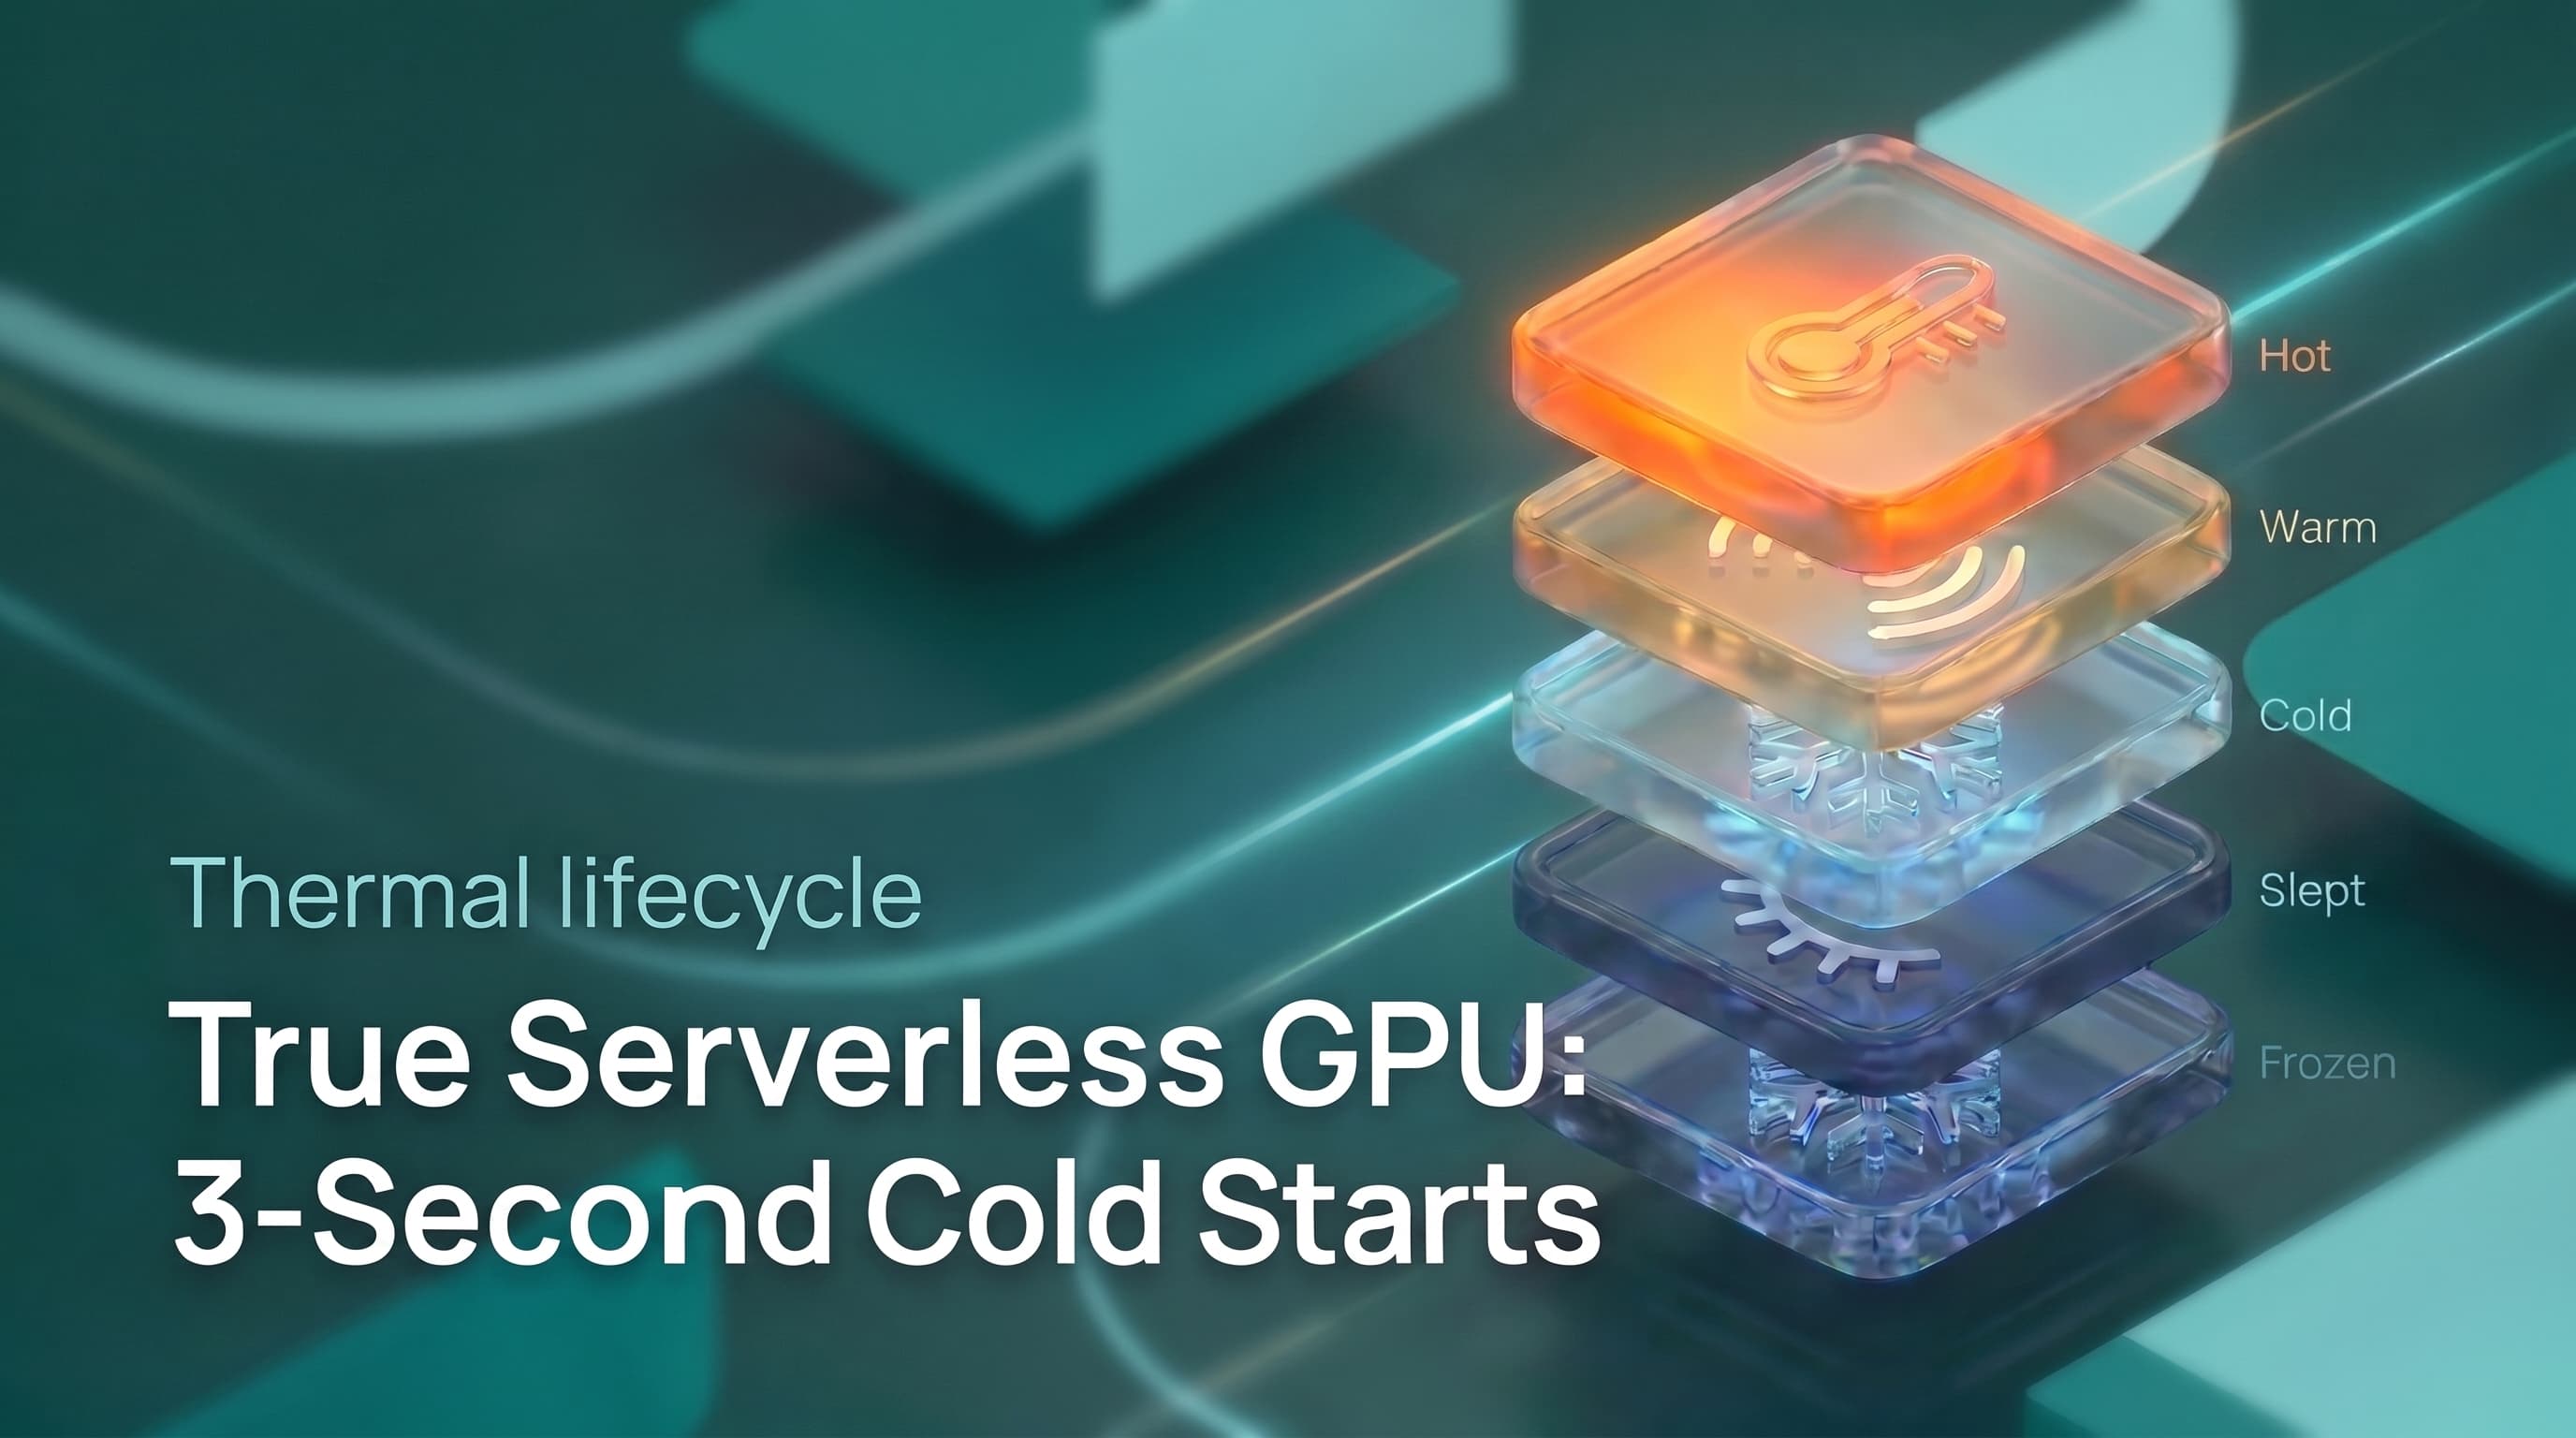
Discover how five compounded optimizations enable 3-second GPU cold starts and true serverless economics for inference workloads.
Learn how to fine-tune a 7B-parameter LLM like Llama 3.1 8B on a single 24GB GPU slice using QLoRA.
Run interactive GPU-backed Jupyter notebooks on affordable slices that auto-idle to save costs.